library(readr)
library(dplyr)
library(tibble)
library(tidyr)
library(stringr)
library(tidytext)
library(ggplot2)

sentences <- read_csv(
  "data/workforce/workforce_sentences.csv",
  na = character(),
  col_types = cols(
    sentence_id = col_character(),
    document_id = col_character(),
    source_line = col_character(),
    text = col_character(),
    reference_label = col_character(),
    uncertainty = col_character(),
    annotator_id = col_character(),
    rationale = col_character(),
    codebook_version = col_character(),
    codebook_hash = col_character(),
    derived = col_character(),
    transformation = col_character()
  )
)

source_counts <- sentences |>
  mutate(source = if_else(document_id == "F001", "training flyer", "job details")) |>
count(source, name = "rows")Counting nearby words with n-grams
Measure sparsity in phrase counts
phrases and entities
n-grams
workforce research
Count adjacent tokens with bigrams and trigrams. Examine rare phrases and the effect of minimum counts on PMI rankings.
Words such as training occur several times in the Riverton Workforce Lab’s job-board lines and flyer headings. The team asks whether adjacent word pairs provide clearer descriptions.
The coordinator examines simple phrase counts. If most phrases appear once, the list may describe these 28 text units but provide little information about new documents.
Note
The author created the fictional Riverton Workforce Lab, its job board, and its training flyer for teaching.
TipWhat you will learn
This lesson shows how to:
- describe an n-gram as a sequence of adjacent tokens.
- build bigrams and trigrams with tidytext.
- count n-gram occurrences in the Riverton text.
- measure how many n-grams appear once.
- score recurring bigrams with pointwise mutual information.
- explain why phrase vocabularies can generalise badly from small data.
Load the sentences
This setup chunk reads the sentence file, prepares small tables, builds n-grams with tidytext, and draws one summary chart. A tibble is a table that prints its size and column types.
| Source | Rows |
|---|---|
| job details | 22 |
| training flyer | 6 |
The small file permits direct inspection. Its phrase counts describe this local example, not a larger population.
Build adjacent-word phrases
An n-gram is a sequence of n adjacent tokens. A unigram has one token, a bigram has two, and a trigram has three. As in Lesson 15, tokenization lowercases text and removes punctuation. Each row contains one source-text unit, and n-grams do not cross rows. Files with whole documents per row need a separate sentence-boundary check.
make_ngrams <- function(n) {
  if (identical(n, 1L)) {
    sentences |>
      select(sentence_id, text) |>
      unnest_tokens(output = ngram, input = text, token = "words") |>
      filter(!is.na(ngram))
  } else {
    sentences |>
      select(sentence_id, text) |>
      unnest_tokens(output = ngram, input = text, token = "ngrams", n = n) |>
      filter(!is.na(ngram))
  }
}

short_for_trigrams <- make_ngrams(1L) |>
  count(sentence_id, name = "tokens") |>
  filter(tokens < 3L)

bigrams <- make_ngrams(2L) |>
  count(ngram, name = "frequency", sort = TRUE)
trigrams <- make_ngrams(3L) |>
  count(ngram, name = "frequency", sort = TRUE)

top_phrases <- bind_rows(
  bigrams |>
    slice_head(n = 8) |>
    mutate(kind = "bigram"),
  trigrams |>
    slice_head(n = 8) |>
    mutate(kind = "trigram")
) |>
select(kind, ngram, frequency)| N-gram type | N-gram | Frequency |
|---|---|---|
| bigram | is required | 4 |
| bigram | training is | 3 |
| bigram | are required | 2 |
| bigram | experience is | 2 |
| bigram | is preferred | 2 |
| bigram | is provided | 2 |
| bigram | no prior | 2 |
| bigram | shifts are | 2 |
| trigram | training is provided | 2 |
| trigram | 12 week training | 1 |
| trigram | a daytime schedule | 1 |
| trigram | a high school | 1 |
| trigram | a medical records | 1 |
| trigram | a paid apprenticeship | 1 |
| trigram | a portfolio is | 1 |
| trigram | a valid driver’s | 1 |
The phrase Evening classes has only two tokens and no trigram. The code removes that empty result before counting. The most frequent bigram is is required, with 4 occurrences. The most frequent trigram is training is provided, with 2.
Measure the sparsity
Sparsity means that many possible items have no examples or only one. Each new word adds at most one word type. It can also add a new pair and a new triple. The number of possible pairs increases faster than vocabulary size. The Riverton counts illustrate this arithmetic argument rather than prove it.
unigrams <- make_ngrams(1L) |>
  count(ngram, name = "frequency", sort = TRUE)

ngram_counts <- list(unigrams, bigrams, trigrams)

ngram_summary <- tibble(
  n = 1:3,
  name = c("unigrams", "bigrams", "trigrams"),
  distinct_items = vapply(ngram_counts, nrow, integer(1)),
  seen_once = vapply(
    ngram_counts,
    \(counts) sum(counts$frequency == 1L),
    integer(1)
  ),
  seen_once_label = str_c(seen_once, "/", distinct_items)
)| n | Unit | Distinct units | Seen once | Seen-once fraction |
|---|---|---|---|---|
| 1 | unigrams | 96 | 72 | 72/96 |
| 2 | bigrams | 112 | 102 | 102/112 |
| 3 | trigrams | 96 | 95 | 95/96 |
The 28 text units contain 96 distinct unigrams, 112 distinct bigrams, and 96 distinct trigrams. The seen-once fractions are 72/96 for unigrams, 102/112 for bigrams, and 95/96 for trigrams. These numbers describe only this teaching corpus.
Show the plotting code
source("R/lesson-figures.R")

plot_data <- ngram_summary |>
  mutate(
    seen_once_share = seen_once / distinct_items,
    bar_label = str_c(
      seen_once, " of ", distinct_items, " (", round(100 * seen_once_share), "%)"
    ),
    name = factor(name, levels = c("trigrams", "bigrams", "unigrams"))
  )

ggplot(plot_data, aes(x = seen_once_share, y = name)) +
  geom_col(fill = lesson_colours[["accent"]], width = 0.62) +
  geom_text(
    aes(label = bar_label),
    hjust = 0,
    nudge_x = 0.015,
    family = lesson_font,
    size = 10,
    size.unit = "pt",
    colour = lesson_colours[["body"]]
  ) +
  scale_x_continuous(expand = expansion(mult = c(0, 0.32))) +
  labs(
    title = "Longer n-grams are almost all one-offs",
    subtitle = "Distinct n-grams seen exactly once in the 28 Riverton sentences",
    x = NULL,
    y = NULL
  ) +
  theme_lesson(grid = "none") +
  theme(axis.text.x = element_blank())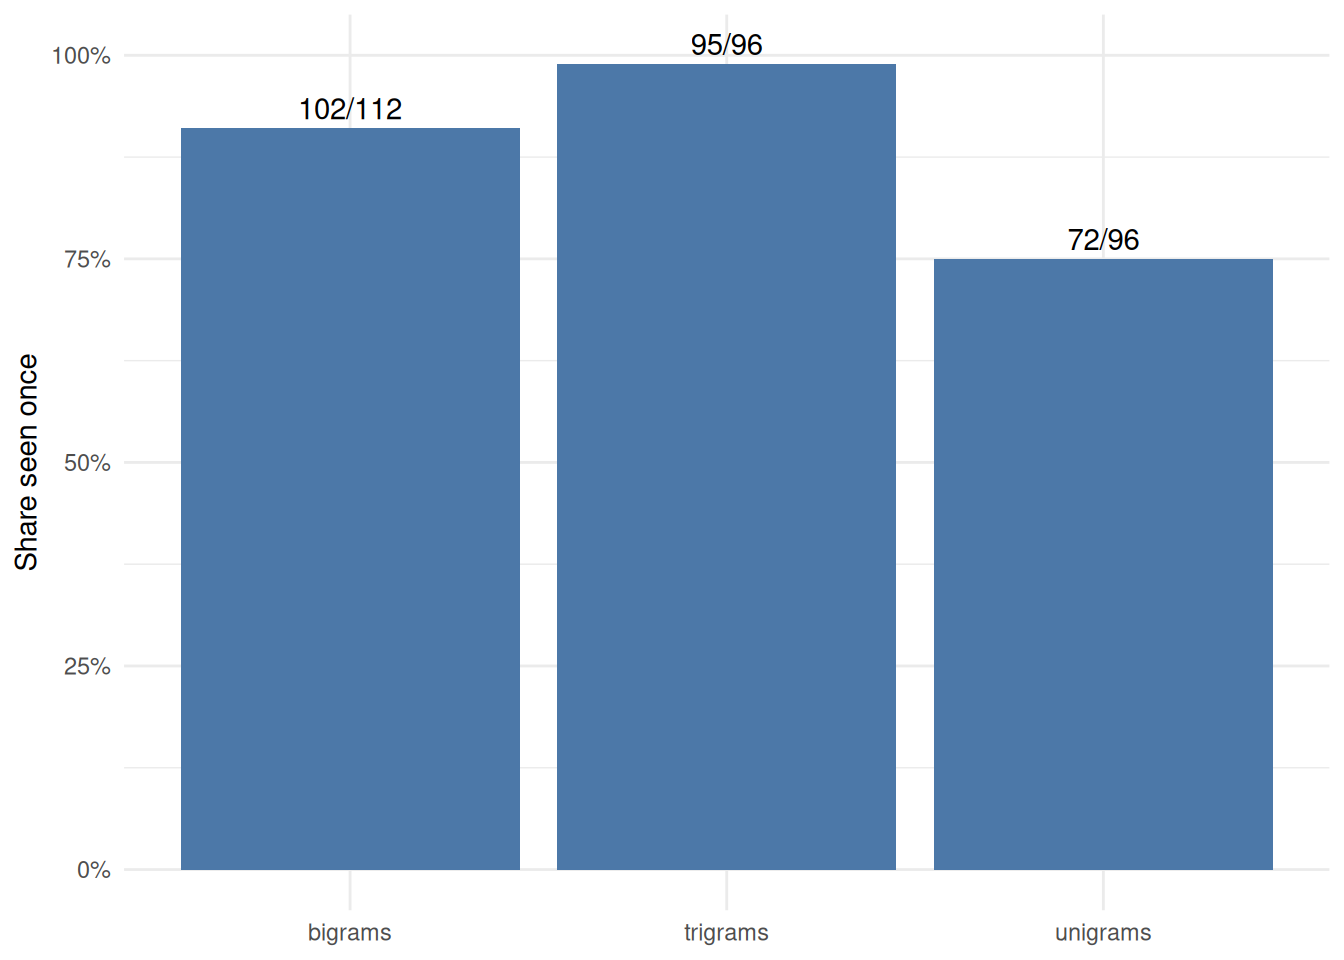
The chart compares the fraction of each list that appears only once.
Score pairs against chance
Raw frequency ranks common words highly. Pointwise mutual information, or PMI, compares an adjacent pair’s frequency with the frequency expected under independent word selection. For a pair (w1, w2):
PMI = log2( P(w1, w2) / (P(w1) * P(w2)) )
The probabilities use shares of 153 unigram tokens and 125 bigram tokens from these 28 text units. If both words appear only once, together, the pair has a small denominator and high score. This follows from the formula. It does not establish that the pair is a stable phrase.
unigram_tokens <- make_ngrams(1L)
bigram_tokens <- make_ngrams(2L)
unigram_n <- nrow(unigram_tokens)
bigram_n <- nrow(bigram_tokens)

unigram_counts <- unigram_tokens |>
  count(ngram, name = "word_n")

pmi_bigrams <- bigram_tokens |>
  separate_wider_delim(
    ngram,
    delim = " ",
    names = c("word1", "word2"),
    too_many = "merge"
  ) |>
  count(word1, word2, name = "pair_n") |>
  left_join(unigram_counts, by = join_by(word1 == ngram)) |>
  rename(word1_n = word_n) |>
  left_join(unigram_counts, by = join_by(word2 == ngram)) |>
  rename(word2_n = word_n) |>
  mutate(
    ngram = str_c(word1, word2, sep = " "),
    pmi = log2(
      (pair_n / bigram_n) /
        ((word1_n / unigram_n) * (word2_n / unigram_n))
    )
  )

hapax_singletons <- pmi_bigrams |>
  filter(pair_n == 1L, word1_n == 1L, word2_n == 1L) |>
  arrange(ngram)

repeated_pmi <- pmi_bigrams |>
  filter(pair_n >= 2L) |>
  arrange(desc(pmi), desc(pair_n), ngram)

hapax_singleton_pmi <- log2(
  (1 / bigram_n) / ((1 / unigram_n) * (1 / unigram_n))
)

is_required <- pmi_bigrams |>
filter(ngram == "is required")| Bigram | Pair count | PMI |
|---|---|---|
| 50 pounds | 1 | 7.55 |
| able to | 1 | 7.55 |
| an essential | 1 | 7.55 |
Thirty-seven of the 102 one-time bigrams contain words that each appear once. They all receive PMI 7.55. The most frequent bigram, is required, appears 4 times and scores 3.04. Its words appear 13 times and 7 times, respectively. A minimum pair count of two retains ten bigrams.
repeated_pmi_table <- repeated_pmi |>
  transmute(
    ngram,
    pair_n,
    pmi = round(pmi, 2)
)| Bigram | Pair count | PMI |
|---|---|---|
| no prior | 2 | 6.55 |
| shifts are | 2 | 5.55 |
| the job | 2 | 5.23 |
| is preferred | 2 | 3.85 |
| is provided | 2 | 3.85 |
| work is | 2 | 3.85 |
| are required | 2 | 3.74 |
| training is | 3 | 3.11 |
| is required | 4 | 3.04 |
| experience is | 2 | 2.85 |
With that minimum count, no prior ranks first and is required ranks ninth. Both lists describe 28 teaching text units. PMI changes the ranking of sparse pairs without removing sparsity. Lesson 25 uses a concordance to examine matches in context instead of ranking them by score.
What to remember
- An n-gram counts adjacent tokens after a chosen token rule.
- The Riverton rows contain 112 distinct bigrams and 96 distinct trigrams.
- A two-token text unit contributes no trigram.
- Without a minimum count, PMI ranks unique word pairs first in this example.
- Counts from 28 text units illustrate sparsity. They do not give an estimate of phrase occurrence in workforce writing.
Report recurring phrases as observations from this example only. The result is a short phrase list with explicit limits from sparse counts.