Run OCR. Compare the result with a known transcript.
source data loading
OCR
workforce research
Learn what optical character recognition can recover from a training flyer and how to measure its errors.
The saved job board supplied digital text. The Riverton Workforce Lab’s next fictional notice is a training flyer available only as an image. Its wording covers a stipend, a class schedule, prior experience, and an application date. Losing or reversing a phrase would change what a person understood about the program.
Optical character recognition, or OCR, gives an estimate of the text in an image. The team will compare OCR output with a known reference transcript. It will keep the image and extracted text. Text recovery precedes classification of the flyer’s claims.
Note
The flyer and program are fictional. The author generated the image for this lesson and wrote the transcript from the image’s source text.
TipWhat you will learn
By the end of this lesson, you will be able to:
explain the difference between digital text and text inside an image.
run the Tesseract OCR engine from R.
compare OCR output with a known reference transcript.
interpret character-level edit distance.
report character and word error rates for a damaged image.
describe conditions that increase OCR errors.
Examine the source image
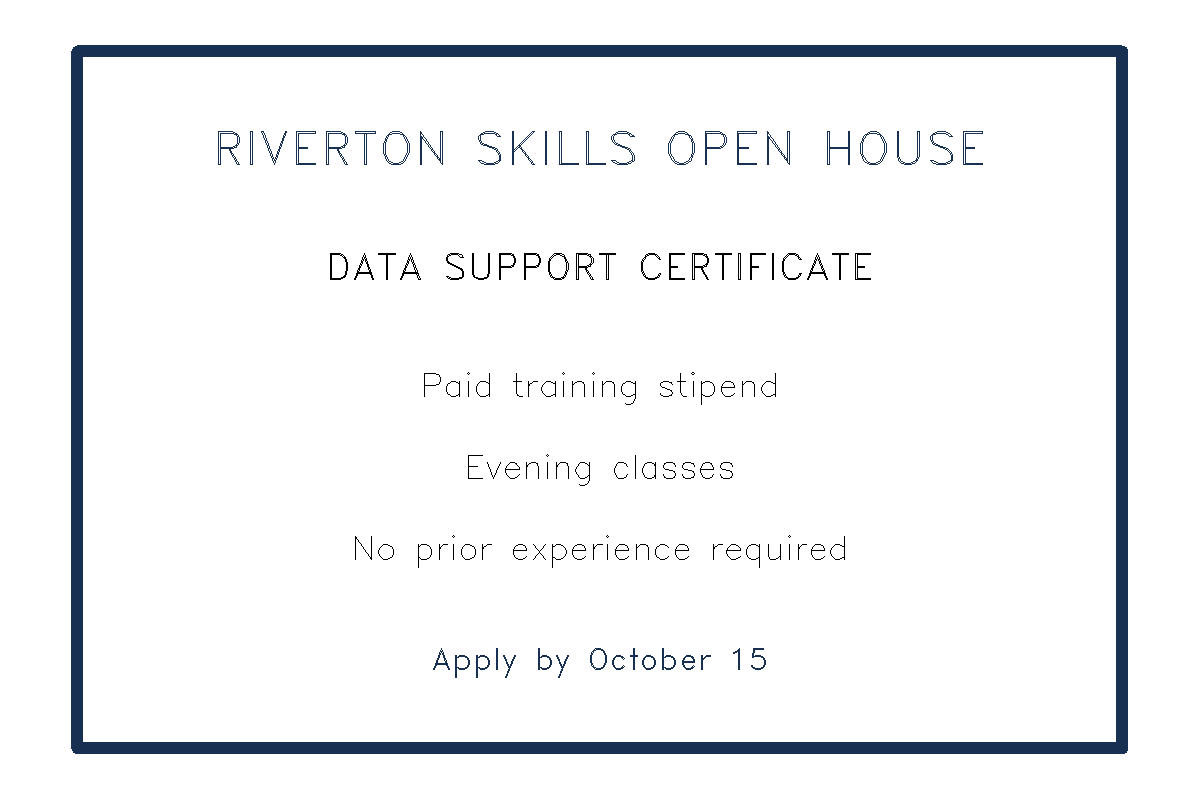
Figure 1: Fictional training flyer used for the OCR example
RIVERTON SKILLS OPEN HOUSE DATA SUPPORT CERTIFICATE Paid training stipend Evening classes No prior experience required Apply by October 15
The adjacent text gives the complete flyer transcript. Readers need that transcript because OCR can make errors or fail to run in their browser. The image remains the source. OCR provides one interpretation of the image.
[1] "RIVERTON SKILLS OPEN HOUSE"   "DATA SUPPORT CERTIFICATE"
[3] "Paid training stipend"        "Evening classes"
[5] "No prior experience required" "Apply by October 15"
The transcript is the comparison source for this controlled example. In real research, qualified readers must examine the reference. Those readers need to understand the document’s language and layout.
Run OCR
The tesseract package connects R to the open-source Tesseract OCR engine. We select English because the flyer is written in English.
[1] "RIVERTON SKILLS OPEN HOUSE"   "DATA SUPPORT CERTIFICATE"
[3] "Paid training stipend"        "Evening classes"
[5] "No prior experience required" "Apply by October 15"
The published transcript uses committed output from native Tesseract 5.3.2. The host engine runs a diagnostic, but its output does not change the displayed transcript or metrics. The exact match applies to this image and software version. It does not establish general OCR accuracy.
The lockfile pins the R package. The native engine and language data come from the operating system, so the lesson reports them at run time. The repository also preserves the raw output recorded with native Tesseract 5.3.2 in data/workforce/training-flyer-ocr-5.3.2.txt.
Measure the difference
Edit distance counts the smallest number of character insertions, deletions, or substitutions needed to convert one text to another. We normalize case and punctuation before comparing because the research question concerns the words, not the flyer styling.
An edit distance of zero means that the normalized texts match exactly. This is not a universal character-error rate. Normalization removed case, punctuation, and line boundaries, and the denominator includes spaces. The code separately requires exact matches for every raw line and the critical experience statement.
Damage the image and measure what is lost
This 1200-pixel-wide flyer at full size represents ideal conditions for the pipeline. Real material can include angled photographs, faxes, low-resolution scans, or prints from failing toner cartridges.
The lesson degrades the image with two reproducible operations. First, it retains every third row and column, reducing each dimension to a third of its original size. Then it lightens every third remaining row to imitate scanner banding.
Both operations use arithmetic on the pixel array without randomness. Each render therefore produces the same file.
The final column reports whether the host engine reproduced each committed transcript. A FALSE value is a local-version difference, while the published metrics below remain tied to the recorded 5.3.2 output.
Character and word error rates
Two standard rates describe this comparison. Character error rate, or CER, divides character-level edit distance by the number of reference characters. Word error rate, or WER, applies the same calculation to whole words. A word with one incorrect letter therefore counts as one word error.
Word-level distance needs a separate calculation because adist() compares characters. The following function fills a cost table. Rows represent reference words, and columns represent observed words. The function returns the value in the final row and column.
Error rates for the source image and its degraded copy
Version
Reference characters
Reference words
CER
WER
source image
138
20
0.000
0.0
degraded copy
138
20
0.558
1.2
The source image scores zero on both rates. The degraded copy does not. Both rates come from committed Tesseract 5.3.2 transcripts, so a native engine upgrade cannot rewrite the published result. The diagnostic comparison above reports whether the local engine produced the same transcripts.
The transcript beside what the degraded image produced
Line
Reference transcript
Degraded reading
1
RIVERTON SKILLS OPEN HOUSE
AIVS SPCR SKILLS OREM FUL Sk
2
DATA SUPPORT CERTIFICATE
LAI SJZRCRE CEAUIF CATE
3
Paid training stipend
viel tras oe, esis
4
Evening classes
Logs se senate
5
No prior experience required
8 he ee eis ites
6
Apply by October 15
Apps ey Oelaber 15
Read the table alongside the rate. A CER of 0.558 means 0.558 character edits per reference character. It does not measure the fraction of information preserved and has no meaningful midpoint. Insertions can increase CER or WER above one. Here, the remaining words do not form a faithful partial transcript.
Both rates compare one transcript with the output for one image. They describe this pair, not OCR performance in general.
The word rate also assumes that spaces separate words. That assumption works for this English flyer but not for Chinese, Japanese, and Thai. Those scripts require a character rate or script-aware segmentation.
OCR errors are not evenly distributed
OCR becomes harder when a source has:
low resolution, blur, shadows, or skew.
handwriting or decorative fonts.
tables, columns, stamps, or text over images.
uncommon symbols or several languages.
damaged pages.
a reading order that is not visually obvious.
An average error rate can hide the error that matters most. Changing "No prior experience required" to "prior experience required" would reverse the meaning while affecting only a few characters. The team must examine important fields directly, not rely on one summary score.
Preserve the source and correction history
Keep:
the source image.
the OCR engine and language settings.
the unedited OCR output.
the reviewed and corrected transcript.
the identity of the reader or process that performed the checks.
any uncertainty about layout or unreadable text.
Do not overwrite raw OCR with corrections. Separate fields make later edits visible and let another reviewer return to the source.
What to remember
Text inside an image must be recognized before ordinary text analysis.
OCR output is an estimate, not a transcription guarantee.
Compare important output with a reference after human checks.
Report character and word error rates. Identify the source image.
One clean image cannot give an estimate of accuracy on damaged material.
Measure errors. Examine cases where errors change meaning.
Preserve the image, raw output, corrected text, and correction history.
The archived job cards and reference transcript provide traceable text about training, schedules, requirements, and skills. Extraction does not explain the meaning of each sentence. Human classification follows, with a versioned annotation codebook to record the decisions.