library(readr)
library(dplyr)
library(tibble)
library(tidyr)
library(purrr)
library(stringr)
library(tidytext)
library(ggplot2)
library(quanteda)

feedback <- read_csv(
  "data/customer_feedback.csv",
  na = character(),
  col_types = cols(
    feedback_id = col_integer(),
    submitted_at = col_date(),
    channel = col_character(),
    rating = col_character(),
    comment = col_character()
  )
) |>
  mutate(
    rating = if_else(rating == "", NA_integer_, as.integer(rating))
)Scoring sentiment in customer comments
Compare a word list with labels from the domain
classification
sentiment analysis
emotion analysis
Learn why sentiment scores from word lists and trained labels can disagree, especially with short feedback.
At the end of the week, Nia receives five customer comments and one blank rating cell. The dashboard needs a quick sentiment score, but short comments can reveal gaps in the scoring method.
One row thanks the service. Another says a parcel arrived late. A third says the sender could not reset a password. The same column contains praise, complaint, and language the English word list will miss.
TipWhat you will learn
By the end of this lesson, you will be able to:
- score comments with the Bing sentiment lexicon.
- count how many comments receive no lexicon match.
- find context failures such as negation and domain wording.
- contrast a lexicon score with labels from the same domain.
- explain why a word score is not a claim about a person’s inner state.
Load the feedback file
The feedback file is fictional. It was written for teaching and contains no real customers, parcels, accounts, or service records.
readr reads the CSV, dplyr and tibble prepare rows, and tidyr handles missing cells. purrr applies scoring across rows, stringr matches words, and tidytext supplies the lexicon. ggplot2 draws a small plot. quanteda supplies the bundled inaugural corpus through the shared helper.
The file initially preserves the blank rating as a string. The project does not let read_csv() infer missing values.
| ID | Submitted | Channel | Rating | Comment |
|---|---|---|---|---|
| 1001 | 2026-08-21 | 5 | Delivery was quick, thank you! | |
| 1002 | 2026-08-22 | web | 4 | The café listing was easy to find. |
| 1003 | 2026-08-23 | chat | NA | I could not reset my password. |
| 1004 | 2026-08-24 | 2 | The parcel arrived late. | |
| 1005 | 2026-08-25 | web | 5 | Muy útil y fácil de usar. |
The blank rating stays visible. Turning it into a zero would invent a rating the customer did not give.
Count sentiment words
A sentiment lexicon is a word list with labels attached. The Bing Liu opinion lexicon in tidytext comes from product-review research by Minqing Hu and Bing Liu. It has 6,786 English words, each marked positive or negative. The source page asks users to cite the work and states research-use terms rather than an open-data licence. A lexicon score counts matches and gives positive words +1 and negative words -1.
bing <- tidytext::get_sentiments("bing")

token_scores <- feedback |>
  tidytext::unnest_tokens(word, comment) |>
  left_join(
    bing,
    by = join_by(word),
    multiple = "all"
  ) |>
  mutate(
    token_score = case_when(
      sentiment == "positive" ~ 1L,
      sentiment == "negative" ~ -1L,
      TRUE ~ 0L
    )
  )

lexicon_scores <- token_scores |>
  summarise(
    matched_words = sum(token_score != 0L),
    lexicon_score = sum(token_score),
    .by = feedback_id
  ) |>
  right_join(feedback, by = join_by(feedback_id)) |>
  mutate(
    matched_words = replace_na(matched_words, 0L),
    lexicon_score = replace_na(lexicon_score, 0L)
  ) |>
  arrange(feedback_id)

zero_match_feedback_ids <- lexicon_scores |>
  filter(matched_words == 0L) |>
pull(feedback_id)| ID | Rating | Matched sentiment words | Lexicon score | Comment |
|---|---|---|---|---|
| 1001 | 5 | 1 | 1 | Delivery was quick, thank you! |
| 1002 | 4 | 1 | 1 | The café listing was easy to find. |
| 1003 | NA | 0 | 0 | I could not reset my password. |
| 1004 | 2 | 0 | 0 | The parcel arrived late. |
| 1005 | 5 | 0 | 0 | Muy útil y fácil de usar. |
In this five-row walkthrough, rows 1003, 1004, and 1005 contain no Bing word at all. Treat those as inspectable examples, not as a rate. The English lexicon misses the Spanish praise in row 1005. It also gives the late parcel complaint no negative word.
Measure missing lexicon matches on a larger corpus
A larger source can show how often the lexicon finds no matching words. The shared inaugural helper returns 1,377 public-domain paragraphs after a 25-word minimum-length filter. Longer documents have more opportunities to contain a lexicon word. The code applies the same Bing list to each paragraph and counts paragraphs without positive or negative matches.
This also demonstrates a domain mismatch. A product-review lexicon does not provide validated sentiment scores for political speeches.
source("R/inaugural-corpus.R")
paragraphs <- inaugural_paragraphs() |>
  mutate(word_count = str_count(paragraph, "\\S+"))

inaugural_lexicon <- paragraphs |>
  select(paragraph_id, paragraph, word_count) |>
  tidytext::unnest_tokens(word, paragraph) |>
  semi_join(bing, by = join_by(word)) |>
  count(paragraph_id, name = "matched_words") |>
  right_join(
    paragraphs |> select(paragraph_id, word_count),
    by = join_by(paragraph_id)
  ) |>
  mutate(matched_words = replace_na(matched_words, 0L))

inaugural_silence <- inaugural_lexicon |>
  summarise(
    paragraphs = n(),
    zero_match_paragraphs = sum(matched_words == 0L),
    zero_match_share = mean(matched_words == 0L),
    median_matched_words = median(matched_words),
    .groups = "drop"
  )

coverage_by_length <- inaugural_lexicon |>
  mutate(
    length_bin = cut(
      word_count,
      breaks = c(0, 24, 49, 99, Inf),
      labels = c("1-24 words", "25-49 words", "50-99 words", "100+ words"),
      right = TRUE
    )
  ) |>
  summarise(
    paragraphs = n(),
    zero_match_paragraphs = sum(matched_words == 0L),
    zero_match_share = mean(matched_words == 0L),
    median_words = median(word_count),
    .by = length_bin
  ) |>
arrange(length_bin)| Paragraphs | Paragraphs with no Bing match | Share with no Bing match | Median matched words |
|---|---|---|---|
| 1377 | 41 | 0.0298 | 6 |
| Paragraph length bin | Paragraphs | Paragraphs with no Bing match | Share with no Bing match | Median words |
|---|---|---|---|---|
| 25-49 words | 441 | 33 | 0.0748 | 35 |
| 50-99 words | 497 | 8 | 0.0161 | 69 |
| 100+ words | 439 | 0 | 0.0000 | 154 |
On the larger corpus, 41 of 1,377 paragraphs have no Bing match, a share of 0.0298 after the 25-word filter. The median paragraph has 6 matched words.
Among 25-49 word paragraphs, 7.48 percent have no match. Among 50-99 word paragraphs, 1.61 percent have no match. None of the 439 paragraphs with at least 100 words lacks a match.
Match coverage increases with document length, as expected. These results do not give an estimate of coverage for the shorter feedback comments from another domain. The 1-24 words bin is empty because the helper retains paragraphs of at least 25 words.
Read the failures before trusting the score
The lexicon scores words without their context. Negation can reverse the meaning of helpful when not appears nearby. A customer-service problem, such as a password reset, may contain no sentiment word. Sarcasm also complicates interpretation because identical words can express sincere praise or criticism.
failure_cases <- lexicon_scores |>
  mutate(
    issue = case_when(
      feedback_id == 1003L ~ "account wording with no matched sentiment word",
      feedback_id == 1004L ~ "domain complaint with no matched word",
      feedback_id == 1005L ~ "non-English praise",
      TRUE ~ NA_character_
    )
  ) |>
  filter(!is.na(issue)) |>
  select(feedback_id, rating, lexicon_score, issue, comment)

thank_tokens <- token_scores |>
  filter(feedback_id == 1001L, word == "thank") |>
  select(word, sentiment, token_score)

negation_examples <- tibble(
  phrase = c("helpful", "not helpful")
) |>
  tidytext::unnest_tokens(word, phrase, drop = FALSE) |>
  left_join(bing, by = join_by(word), multiple = "all") |>
  mutate(
    token_score = case_when(
      sentiment == "positive" ~ 1L,
      sentiment == "negative" ~ -1L,
      TRUE ~ 0L
    )
  ) |>
  summarise(
    matched_words = sum(token_score != 0L),
    lexicon_score = sum(token_score),
    .by = phrase
)| ID | Rating | Lexicon score | Failure type | Comment |
|---|---|---|---|---|
| 1003 | NA | 0 | account wording with no matched sentiment word | I could not reset my password. |
| 1004 | 2 | 0 | domain complaint with no matched word | The parcel arrived late. |
| 1005 | 5 | 0 | non-English praise | Muy útil y fácil de usar. |
| Phrase | Matched sentiment words | Lexicon score |
|---|---|---|
| helpful | 1 | 1 |
| not helpful | 1 | 1 |
Row 1003 concerns account access and contains no matched sentiment word. The separate not helpful example receives the same score as helpful. The rule counts positive helpful without reversing its score for not. Row 1001 shows another limit. The positive word thank alone does not distinguish sincere, routine, or sarcastic thanks.
Train on labels from the setting
A trained approach starts with labels from the relevant setting. This demonstration derives labels from three ratings. Ratings of 5 become satisfied, and rating 2 becomes frustrated. The mild rating of 4 is excluded. The seed before this deterministic fit is 4901.
The score uses an equal-prior, Laplace-smoothed multinomial naive Bayes calculation. Adding one to every word count prevents an unseen word from making a class probability zero. Equal priors give the two labels the same initial weight rather than use the two-to-one imbalance in training rows. A deployed classifier must state that prior choice.
set.seed(4901)
labeled_feedback <- feedback |>
  filter(!is.na(rating), rating != 4L) |>
  mutate(
    sentiment_label = factor(
      if_else(rating >= 5L, "satisfied", "frustrated"),
      levels = c("frustrated", "satisfied")
    )
  )

training_tokens <- labeled_feedback |>
  select(feedback_id, sentiment_label, comment) |>
  tidytext::unnest_tokens(word, comment) |>
  count(sentiment_label, word, name = "label_word_count")

vocabulary <- training_tokens |>
  distinct(word) |>
  arrange(word)

label_totals <- training_tokens |>
  summarise(total_words = sum(label_word_count), .by = sentiment_label)

word_rates <- expand_grid(
  sentiment_label = levels(labeled_feedback$sentiment_label),
  word = vocabulary$word
) |>
  left_join(training_tokens, by = join_by(sentiment_label, word)) |>
  mutate(label_word_count = replace_na(label_word_count, 0L)) |>
  left_join(label_totals, by = join_by(sentiment_label)) |>
  mutate(
    word_rate = (label_word_count + 1) /
      (total_words + nrow(vocabulary))
  )

score_with_labels <- function(comment) {
  words <- tibble(comment = comment) |>
    tidytext::unnest_tokens(word, comment) |>
    semi_join(vocabulary, by = join_by(word))

  if (nrow(words) == 0L) {
    return(0)
  }

  joined <- words |>
    count(word, name = "n") |>
    left_join(word_rates, by = join_by(word), multiple = "all")

  totals <- joined |>
    summarise(
      log_score = sum(n * log(word_rate)),
      .by = sentiment_label
    )

  satisfied <- totals |>
    filter(sentiment_label == "satisfied") |>
    pull(log_score)
  frustrated <- totals |>
    filter(sentiment_label == "frustrated") |>
    pull(log_score)

  satisfied - frustrated
}

trained_scores <- feedback |>
  mutate(
    training_role = case_when(
      feedback_id %in% labeled_feedback$feedback_id ~ "fitting row",
      feedback_id == 1002L ~ "excluded mild rating (no reference label)",
      TRUE ~ "unrated row"
    ),
    trained_score = map_dbl(comment, score_with_labels),
    trained_label = case_when(
      trained_score > 0 ~ "satisfied",
      trained_score < 0 ~ "frustrated",
      TRUE ~ "no seen training words"
    )
  ) |>
  select(feedback_id, rating, training_role, comment, trained_score, trained_label) |>
  left_join(
    lexicon_scores |> select(feedback_id, lexicon_score),
    by = join_by(feedback_id)
  ) |>
relocate(lexicon_score, .before = trained_score)| ID | Rating | Training role | Comment | Lexicon score | Rating-trained score | Rating-trained label |
|---|---|---|---|---|---|---|
| 1001 | 5 | fitting row | Delivery was quick, thank you! | 1 | 1.897 | satisfied |
| 1002 | 4 | excluded mild rating (no reference label) | The café listing was easy to find. | 1 | -0.627 | frustrated |
| 1003 | NA | unrated row | I could not reset my password. | 0 | 0.000 | no seen training words |
| 1004 | 2 | fitting row | The parcel arrived late. | 0 | -4.027 | frustrated |
| 1005 | 5 | fitting row | Muy útil y fácil de usar. | 0 | 2.277 | satisfied |
This scorer uses only three labelled rows, so it demonstrates calculations rather than evaluation. Rows 1001, 1004, and 1005 are fitting rows. Reporting performance on those rows would be resubstitution, meaning evaluation on training examples.
Row 1002 is excluded because its mild rating has no reference label in this two-class scheme. The scorer still returns frustrated, but no reference answer exists for scoring that prediction. This is inspection output rather than held-out evaluation.
A larger trained model can use context when its training labels represent the relevant domain. The team must collect those labels. It must make sure the labels are correct. It must also update them as language changes.
Emotion needs stronger evidence
Sentiment is usually a coarse positive-negative score. Emotion analysis asks for labels such as anger, fear, sadness, joy, or surprise. That claim is much stronger.
score_range <- lexicon_scores |>
  summarise(
    lowest = min(lexicon_score),
    highest = max(lexicon_score),
    distinct_scores = n_distinct(lexicon_score),
    .groups = "drop"
  )

score_plot <- lexicon_scores |>
count(lexicon_score, name = "comments")| Lexicon score | Comments |
|---|---|
| 0 | 3 |
| 1 | 2 |
Show the plotting code
source("R/lesson-figures.R")

ggplot(
  score_plot,
  aes(x = comments, y = str_c("score ", lexicon_score))
) +
  geom_col(fill = lesson_colours[["accent"]], width = 0.6) +
  geom_text(
    aes(label = str_c(comments, " comments")),
    hjust = 0,
    nudge_x = 0.05,
    family = lesson_font,
    size = 10,
    size.unit = "pt",
    colour = lesson_colours[["body"]]
  ) +
  scale_x_continuous(expand = expansion(mult = c(0, 0.35))) +
  labs(
    title = "Five comments receive only two lexicon scores",
    subtitle = "Bing lexicon score for each fictional feedback comment",
    x = NULL,
    y = NULL
  ) +
  theme_lesson(grid = "none") +
  theme(axis.text.x = element_blank())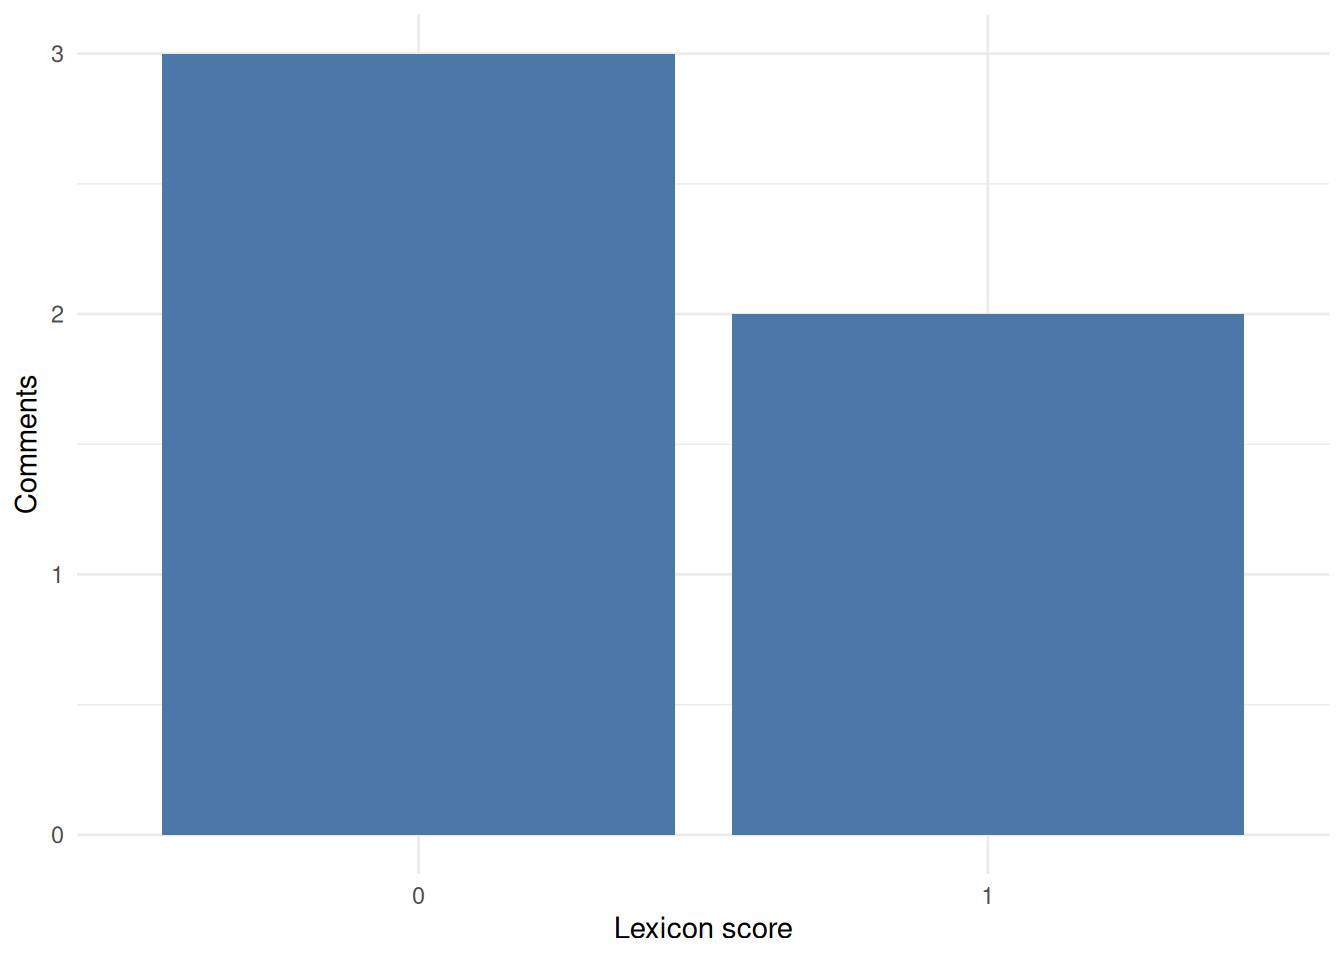
A positive-word count is not an emotion. Self-reported emotion and observed emotion can differ, and neither appears in this file. A score such as 0.62 describes words or model output. It does not establish a person’s internal emotional state.
What to remember
- A sentiment lexicon counts words it recognizes.
- On the 25-word-filtered inaugural corpus, 41 of 1,377 paragraphs have no Bing match. Missing matches become less common as paragraph length increases.
- Negation, language, domain wording, and sarcasm can cause incorrect word-count scores.
- A trained approach needs labels from the setting it will serve.
- Emotion claims require evidence beyond positive and negative words.
Sources
- tidytext sentiment lexicons
- Bing Liu opinion lexicon, created for product-review sentiment research by Minqing Hu and Bing Liu. The source page requests citation and states research-use terms.
- tidytext text mining book