suppressPackageStartupMessages({
  library(dplyr)
  library(tibble)
  library(stringr)
  library(tidyr)
  library(stopwords)
  library(ggplot2)
  library(rsample)
  library(recipes)
  library(textrecipes)
  library(parsnip)
  library(workflows)
  library(yardstick)
  library(broom)
  library(glmnet)
})

source("R/inaugural-corpus.R")
paragraphs <- inaugural_paragraphs()

set.seed(4301)
era_split <- group_initial_split(paragraphs, group = speech_id, prop = 0.75)
era_training <- training(era_split)
era_testing <- testing(era_split)

era_recipe <- recipe(era ~ paragraph, data = era_training) |>
  step_tokenize(paragraph) |>
  step_stopwords(paragraph) |>
  step_tokenfilter(paragraph, max_tokens = 500) |>
  step_tfidf(paragraph)

era_model <- logistic_reg(penalty = 0.01, mixture = 0) |>
  set_engine("glmnet")

era_workflow <- workflow() |>
  add_recipe(era_recipe) |>
  add_model(era_model)

set.seed(4302)
era_fitted <- fit(era_workflow, data = era_training)

held_out_predictions <- predict(era_fitted, era_testing) |>
  bind_cols(era_testing |> select(era))

held_out_accuracy <- accuracy(
  held_out_predictions,
  truth = era,
  estimate = .pred_class
) |>
  pull(.estimate)

era_length_summary <- paragraphs |>
  group_by(era) |>
  summarise(
    paragraphs = n(),
    median_words = median(paragraph_words),
    .groups = "drop"
)Monitoring models
Monitoring after initial evaluation
model development
monitoring
model drift
Learn how to measure model performance across time slices and why different labels can make an old score misleading.
A model passes its initial evaluation, and its API is ready to score paragraphs.
Three months later, the incoming paragraphs differ. Their words and file format remain familiar, and the deployment record still contains the original score. Those facts do not establish unchanged performance.
Monitoring examines differences after deployment. It can compare incoming text with training text. When the team makes sure the labels are correct, monitoring can also measure prediction performance.
TipWhat you will learn
This lesson shows how to:
- score a fitted text model across time slices.
- read held-out slice scores without treating them as a new train/test study.
- measure input drift when labels are late or missing.
- explain concept drift in plain language.
- explain why a fixed party text model needs fresh evidence.
- name what monitoring can and cannot see.
Refit the era model
For a monitoring lesson, we replay the corpus as if labeled paragraphs arrived from different periods. The model is the same penalized logistic regression with tf-idf features. The split seed is 4301, and the fit seed is 4302.
| Item | Value |
|---|---|
| paragraphs | 1377 |
| held-out paragraphs | 335 |
| held-out accuracy | 0.8209 |
The held-out score is still the evaluation score. Any slice score below uses only those 335 held-out paragraphs, never rows from the training side.
Score held-out time slices
A monitoring slice is a subset assessed separately, such as a month, region, source, or time period. This lesson uses historical periods. However, the era label comes from year, so time-based slices also separate labels. A slice with one label measures that class’s recall rather than overall performance.
period_breaks <- c(1780, 1849, 1899, 1949, 1999, 2030)
period_levels <- c(
  "1789-1849",
  "1850-1899",
  "1900-1949",
  "1950-1999",
  "2000-2025"
)

held_out_by_period <- held_out_predictions |>
  bind_cols(era_testing |> select(paragraph_id, year, paragraph)) |>
  mutate(
    period = cut(
      year,
      breaks = period_breaks,
      labels = period_levels,
      right = TRUE
    )
  )

label_counts <- held_out_by_period |>
  count(period, era, name = "labels") |>
  complete(
    period = factor(period_levels, levels = period_levels),
    era = levels(paragraphs$era),
    fill = list(labels = 0L)
  )

period_accuracy <- label_counts |>
  group_by(period) |>
  summarise(
    held_out_paragraphs = sum(labels),
    before_1900 = sum(labels[era == "before 1900"]),
    later_1900 = sum(labels[era == "1900 or later"]),
    .groups = "drop"
  ) |>
  left_join(
    held_out_by_period |>
      group_by(period) |>
      summarise(
        correct = sum(.pred_class == era),
        accuracy = mean(.pred_class == era),
        .groups = "drop"
      ),
    by = join_by(period)
  ) |>
  mutate(
    correct = if_else(is.na(correct), 0L, as.integer(correct)),
    score_kind = case_when(
      held_out_paragraphs == 0L ~ "no held-out rows",
      before_1900 == 0L | later_1900 == 0L ~ "one-class recall",
      TRUE ~ "two-class accuracy"
    )
  )

lowest_slice <- period_accuracy |>
  filter(held_out_paragraphs > 0L) |>
slice_min(accuracy, n = 1, with_ties = FALSE)| Period | Held-out paragraphs | Before 1900 labels | 1900 or later labels | Correct | Score type | Accuracy |
|---|---|---|---|---|---|---|
| 1789-1849 | 67 | 67 | 0 | 58 | one-class recall | 0.866 |
| 1850-1899 | 128 | 128 | 0 | 87 | one-class recall | 0.680 |
| 1900-1949 | 23 | 0 | 23 | 17 | one-class recall | 0.739 |
| 1950-1999 | 117 | 0 | 117 | 113 | one-class recall | 0.966 |
| 2000-2025 | 0 | 0 | 0 | 0 | no held-out rows | NA |
The lowest held-out slice is 1850-1899, with 128 paragraphs and accuracy 0.68. It is not the slice around 1900. Every nonempty slice contains one class. The table therefore demonstrates circular monitoring, where the monitoring groups depend on the variable used to assign the label. It is not a general accuracy report.
The 2000-2025 row is empty because all speeches from that period entered the training set under seed 4301. Grouped splitting keeps whole speeches together, so a period can have no held-out examples even when the full corpus contains them.
Watch input drift without waiting for labels
Labels often arrive late or remain unavailable. A team can still compare incoming text with the text used for model fitting. The code treats the 500 model features as the training vocabulary. It measures the share of non-stopword tokens outside that vocabulary and reports median paragraph length.
This retrospective teaching check uses the full corpus. Most rows helped select the vocabulary, so the results favour familiar terms. Live monitoring should assess only later, unseen text.
training_vocabulary <- tidy(extract_fit_parsnip(era_fitted)) |>
  filter(term != "(Intercept)") |>
  transmute(token = str_remove(term, "^tfidf_paragraph_")) |>
  pull(token)

period_paragraphs <- paragraphs |>
  mutate(
    period = cut(
      year,
      breaks = period_breaks,
      labels = period_levels,
      right = TRUE
    )
  )

period_lengths <- period_paragraphs |>
  group_by(period) |>
  summarise(
    paragraphs = n(),
    median_words = median(paragraph_words),
    .groups = "drop"
  )

model_stop_words <- tibble(
  word = stopwords("en", source = "snowball")
)

drift_table <- period_paragraphs |>
  select(paragraph_id, period, paragraph) |>
  # Tokenise with an explicit pattern rather than `unnest_tokens()`. The default
  # word tokeniser uses ICU word boundaries, and ICU versions differ between
  # machines, so the same text can yield slightly different token counts on a
  # Linux runner than on a laptop. A stated pattern makes the count reproducible.
  mutate(token = str_extract_all(tolower(paragraph), "[a-z']+")) |>
  select(-paragraph) |>
  unnest_longer(token) |>
  anti_join(model_stop_words, by = join_by(token == word)) |>
  group_by(period) |>
  summarise(
    tokens = n(),
    absent_tokens = sum(!(token %in% training_vocabulary)),
    absent_share = absent_tokens / tokens,
    .groups = "drop"
  ) |>
  left_join(period_lengths, by = join_by(period)) |>
select(period, paragraphs, median_words, tokens, absent_tokens, absent_share)| Period | Paragraphs | Median words | Non-stopword tokens | Tokens outside 500 features | Share outside 500 features |
|---|---|---|---|---|---|
| 1789-1849 | 220 | 149.5 | 19192 | 9900 | 0.516 |
| 1850-1899 | 265 | 92.0 | 14562 | 7390 | 0.507 |
| 1900-1949 | 317 | 67.0 | 14388 | 7014 | 0.487 |
| 1950-1999 | 371 | 53.0 | 10650 | 4972 | 0.467 |
| 2000-2025 | 204 | 43.0 | 5579 | 2800 | 0.502 |
The stop-word list now matches step_stopwords() in the fitted recipe: the Snowball English list supplied by the stopwords package.
The explicit regular expression differs from the fitted recipe’s step_tokenize() tokenizer. It makes this lesson reproducible across ICU versions. However, absent_share approximates feature coverage and can reflect tokenization differences as well as vocabulary drift.
The vocabulary measure varies little partly because it uses a fixed 500-token list. About half of the non-stopword tokens are outside that list. The share ranges from 0.467 to 0.516 across 236 years. These historical shares combine training and held-out rows. They are not an out-of-sample drift estimate.
Median paragraph length varies more clearly. It decreases from 149.5 words in the earliest period to 43 in the latest. Paragraph length also contributed to the era result in the evaluation lesson.
Before-1900 paragraphs have median length 112. Later paragraphs have median length 54. A vocabulary-only check would miss that difference.
Neither check requires labels, so both can execute before samples with reference labels arrive. Neither establishes that the model remains correct. They compare incoming text with the model’s training text. A model can still make serious errors on familiar-looking input.
Show the plotting code
source("R/lesson-figures.R")

drift_plot <- drift_table |>
  transmute(
    period,
    `Median words per paragraph` = median_words,
    `Share of non-stopword tokens outside the 500 training features` = absent_share
  ) |>
  pivot_longer(
    cols = -period,
    names_to = "measure",
    values_to = "value"
  ) |>
  mutate(
    value_label = if_else(
      str_detect(measure, "^Share"),
      scales::percent(value, accuracy = 1),
      as.character(value)
    )
  )

# Both panels start at zero, so the nearly flat share does not look like a
# large change just because its panel has its own scale. The zero line is the
# only reference line; the labels carry the values.
panel_floor <- tibble(measure = unique(drift_plot$measure), value = 0)

ggplot(drift_plot, aes(x = period, y = value, group = measure)) +
  geom_blank(data = panel_floor, aes(x = NULL, group = NULL)) +
  geom_hline(
    yintercept = 0,
    colour = lesson_colours[["context"]],
    linewidth = 0.5
  ) +
  geom_line(colour = lesson_colours[["accent"]], linewidth = 0.9) +
  geom_point(colour = lesson_colours[["accent"]], size = 2.6) +
  geom_text(
    aes(label = value_label),
    vjust = -1,
    family = lesson_font,
    size = 9.5,
    size.unit = "pt",
    colour = lesson_colours[["body"]]
  ) +
  facet_wrap(vars(measure), scales = "free_y", ncol = 1) +
  scale_y_continuous(expand = expansion(mult = c(0, 0.3))) +
  labs(
    title = "Paragraph length varies more than vocabulary coverage",
    subtitle = "Two label-free input checks for each period of the inaugural corpus. Both panels start at zero.",
    x = "Period",
    y = NULL
  ) +
  theme_lesson(grid = "none") +
  theme(axis.text.y = element_blank())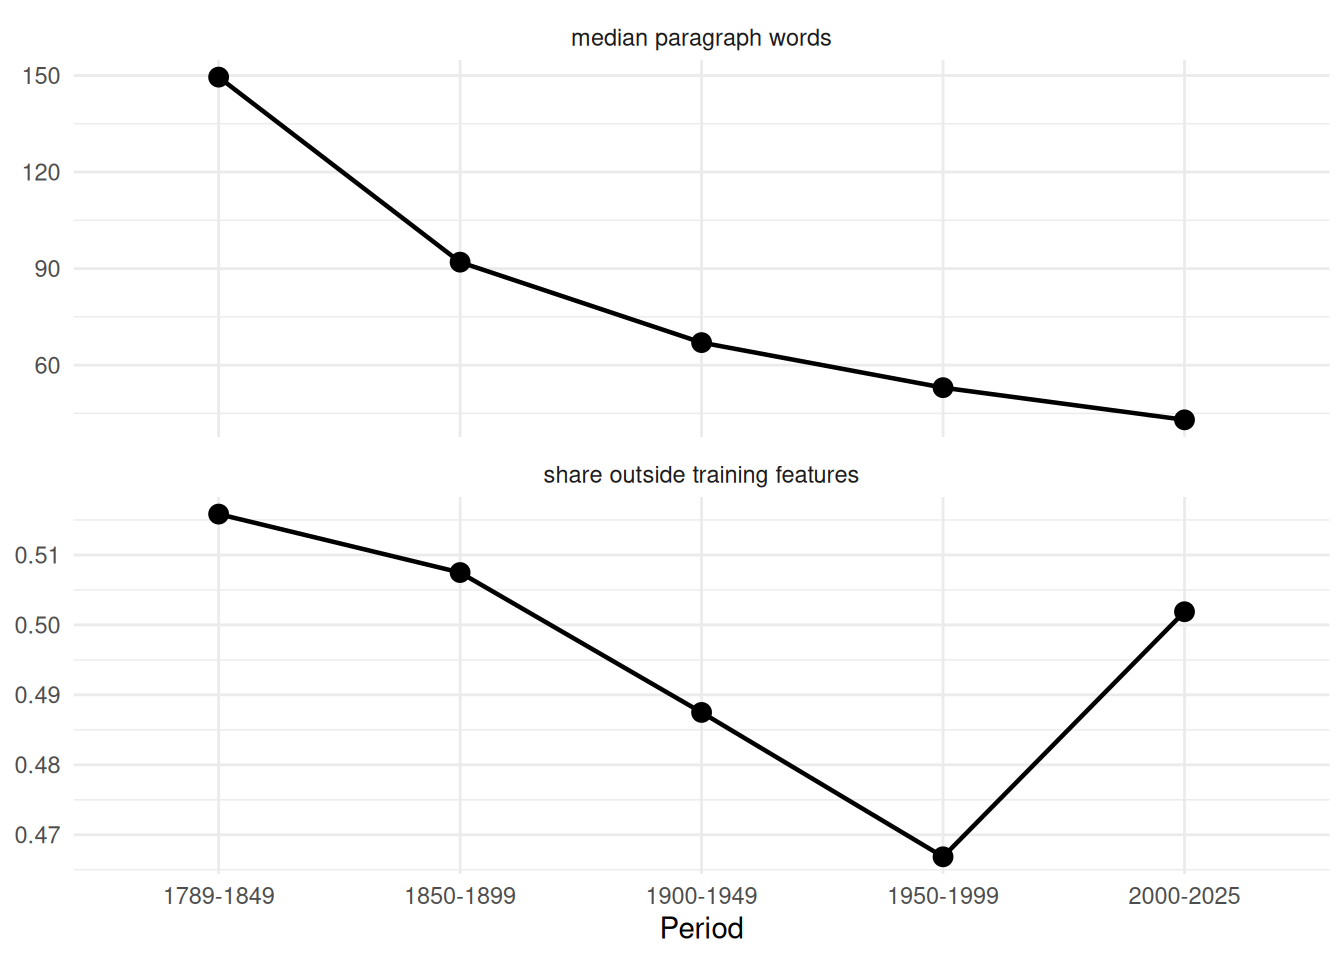
The length pattern varies more than the absent-token share here. Either difference could require a check in a live system. Neither difference alone proves that the model is wrong. Each shows an input difference for a person to examine.
Watch labels as well as words
Concept drift means the relationship between inputs and labels changes over time. Text changes when writers choose new words. Labels can change too.
The party column in this corpus spans the full address range. A label such as Democratic appears across many decades. That span is not evidence that one fixed paragraph model can predict party across the collection. The evaluation result for this recipe and penalty is a measurement warning, not a political finding.
party_range <- paragraphs |>
  summarise(
    first_year = min(year),
    last_year = max(year),
    years_spanned = last_year - first_year,
    parties = n_distinct(party),
    .groups = "drop"
  )

democratic_range <- paragraphs |>
  filter(party == "Democratic") |>
  summarise(
    first_year = min(year),
    last_year = max(year),
    paragraphs = n(),
    speeches = n_distinct(speech_id),
    .groups = "drop"
  )

party_rows <- paragraphs |>
filter(party %in% c("Democratic", "Republican"))| Labels included | First year | Last year | Paragraphs |
|---|---|---|---|
| all party labels | 1789 | 2025 | 1377 |
| Democratic | 1829 | 2021 | 471 |
Monitoring can detect differences in input distributions. It can also detect lower scores when the team makes sure reference labels are correct. It cannot find confident errors on questions that nobody examines. Monitoring therefore needs people to examine a sample of predictions. It also needs dashboards.
What to remember
- Monitoring starts after a team packages a model or starts to operate it routinely.
- Slice scores can show where performance changes.
- A slice score is not the same as a new held-out evaluation.
- Concept drift means the relationship between inputs and labels changes over time.
- Monitoring cannot find errors in rows that no one examines.
Continue to examine model results even when a dashboard has no alerts.