library(dplyr)
library(tibble)
library(tidyr)
library(purrr)
library(stringr)
library(igraph)
library(tidygraph)
library(ggplot2)
library(ggraph)
library(tidytext)

source("R/inaugural-corpus.R")
source("R/lesson-figures.R")

nodes <- tribble(
  ~node_id, ~label, ~node_type,
  "ORG-0002", "Riverton Skills Centre", "organisation",
  "ORG-0003", "Marrow County Transit", "organisation",
  "LOC-0001", "Riverton", "place",
  "LOC-0002", "Riverton", "place",
  "LOC-0003", "Bellhaven", "place",
  "CRD-0002", "Data Support Certificate", "credential",
  "VALUE-October 15", "October 15", "date literal",
  "VALUE-November 1", "November 1", "date literal"
)

edges <- tribble(
  ~from, ~to, ~relation, ~document_ids,
  "ORG-0002", "CRD-0002", "offers", "A001; A002",
  "ORG-0002", "VALUE-October 15", "application_deadline", "A003",
  "ORG-0002", "VALUE-November 1", "application_deadline", "A004"
)Drawing a knowledge graph
Use IDs, arrows, labels, and tables before reading a layout
information visualization
knowledge graph visualization
networks
Learn how to draw a small knowledge graph with ggraph in R. Keep identifiers, edge labels, layout limits, and text alternatives visible.
Chloe wants to follow relationships in a table of Riverton facts. Which organisation offers the credential? Which deadline values remain for human checks? Which place label could merge distinct places if the graph ignored IDs?
Knowledge graph visualization draws entities as nodes and typed relations as edges. In this lesson, the edges are directed and labelled because the relation itself is part of the data.
A drawing can help Chloe see a path. It can also mislead her if she treats the layout as a measurement. The table of edges remains the source of the graph.
Note
The Riverton entities and facts in this lesson are fictional teaching records rebuilt from the earlier knowledge base example.
TipWhat you will learn
By the end of this lesson, you will be able to:
- identify graph nodes by entity ID instead of display label
- show how label-based keys incorrectly merge two Riverton places
- draw directed, labelled edges with ggraph, the ggplot2 extension for networks
- explain why layout coordinates can differ without a change in graph data
- give a captioned edge table as the text alternative
- compare a co-word network with a typed knowledge graph.
Rebuild the graph facts by ID
The graph starts with the populated fact edges named in the knowledge-base lesson. The two Riverton places have different IDs. That difference is the first thing the drawing must preserve.
| From | Relation | To | Source documents |
|---|---|---|---|
| Riverton Skills Centre (ORG-0002) | offers | Data Support Certificate (CRD-0002) | A001; A002 |
| Riverton Skills Centre (ORG-0002) | application deadline | October 15 (VALUE-October 15) | A003 |
| Riverton Skills Centre (ORG-0002) | application deadline | November 1 (VALUE-November 1) | A004 |
The table provides the graph’s long description. It lists IDs and labels for every edge, so readers can examine relations without the picture. The knowledge base retains both deadline values as a dated conflict for human checks. It does not select one automatically. The labels omit years because the announcements say only October 15 and November 1.
Show the label-keyed mistake
If the graph used labels as node keys, both Riverton records would merge into one node. A later fact about either place would then appear to describe the other place too.
id_graph <- tbl_graph(
  nodes = nodes |> rename(name = node_id),
  edges = edges,
  directed = TRUE,
  node_key = "name"
)

label_edges <- edges |>
  left_join(nodes |> select(from = node_id, from_label = label), by = "from") |>
  left_join(nodes |> select(to = node_id, to_label = label), by = "to") |>
  transmute(from = from_label, to = to_label, relation)

label_keyed_graph <- graph_from_data_frame(
  d = label_edges,
  directed = TRUE,
  vertices = nodes |> distinct(name = label)
)

merge_check <- tibble(
  key_used = c("entity ID", "display label"),
  vertices = c(vcount(id_graph), vcount(label_keyed_graph)),
  riverton_vertices = c(
    sum(V(id_graph)$label == "Riverton"),
    sum(V(label_keyed_graph)$name == "Riverton")
  )
)| Key used | Vertices | Vertices displayed as Riverton |
|---|---|---|
| entity ID | 8 | 2 |
| display label | 7 | 1 |
tbl_graph() from tidygraph builds the graph from the two tables, with the entity ID as the node key. The ID-keyed graph has eight vertices. The label-keyed graph has seven because it merges the two places named Riverton.
name_clash <- nodes |>
  summarise(
    ids_with_label = n(),
    entity_ids = str_c(node_id, collapse = "; "),
    entity_types = str_c(node_type, collapse = "; "),
    .by = label
  ) |>
  filter(ids_with_label > 1L)

unconnected_nodes <- nodes |>
filter(!node_id %in% c(edges$from, edges$to))| Shared label | IDs with label | Entity IDs | Entity types |
|---|---|---|---|
| Riverton | 2 | LOC-0001; LOC-0002 | place; place |
| Node ID | Label | Type |
|---|---|---|
| ORG-0003 | Marrow County Transit | organisation |
| LOC-0001 | Riverton | place |
| LOC-0002 | Riverton | place |
| LOC-0003 | Bellhaven | place |
The figure draws 4 nodes that have no populated fact yet. It places them in its bottom row, and the table above names them.
Place nodes by hand and draw arrows
ggraph draws graphs with the same graphics grammar as ggplot2. A layout gives each node a position. geom_edge_*() layers draw edges, and geom_node_*() layers draw nodes. The author specifies this layout manually, so positions remain fixed across renders.
The bottom row contains nodes with no populated fact. Apart from that row, position, rotation, and reflection represent no data. Count links in the table if you need a number. Viewers tend to interpret central nodes as more important. Do not treat this layout as an importance score.
hand_layout <- tribble(
  ~name, ~x, ~y,
  "ORG-0002", 0.0, 0.0,
  "CRD-0002", -3.2, 1.9,
  "VALUE-October 15", 3.2, 1.9,
  "VALUE-November 1", 3.2, -1.7,
  "LOC-0001", -3.6, -3.6,
  "LOC-0002", -1.2, -3.6,
  "ORG-0003", 1.2, -3.6,
  "LOC-0003", 3.6, -3.6
)

node_type_fills <- c(
  organisation = "#D6E6F4",
  credential = "#D5EFE6",
  "date literal" = "#FBE3CF",
  place = "#E6E9ED"
)

riverton_graph <- id_graph |>
  activate(nodes) |>
  left_join(hand_layout, by = "name") |>
  mutate(display_label = str_c(label, "\n", name)) |>
  activate(edges) |>
  mutate(relation_label = str_replace_all(relation, "_", " "))

graph_plot <- ggraph(
  riverton_graph,
  layout = "manual",
  x = x,
  y = y
) +
  geom_edge_link(
    aes(
      label = relation_label,
      start_cap = label_rect(node1.display_label, fontsize = 11, fontfamily = lesson_font),
      end_cap = label_rect(node2.display_label, fontsize = 11, fontfamily = lesson_font)
    ),
    arrow = arrow(type = "closed", length = unit(3, "mm")),
    angle_calc = "along",
    label_dodge = unit(3.2, "mm"),
    label_size = 3.4,
    family = lesson_font,
    edge_colour = lesson_colours[["body"]],
    edge_width = 0.5
  ) +
  geom_node_label(
    aes(label = display_label, fill = node_type),
    family = lesson_font,
    size = 3.8,
    lineheight = 1.05,
    colour = lesson_colours[["ink"]],
    label.padding = unit(0.35, "lines"),
    label.r = unit(0.2, "lines"),
    key_glyph = "rect"
  ) +
  scale_fill_manual(values = node_type_fills, name = "Node type") +
  coord_cartesian(clip = "off") +
  scale_x_continuous(expand = expansion(add = 1.2)) +
  scale_y_continuous(expand = expansion(add = 0.6)) +
  labs(
    title = "Facts connect IDs, so the two places named Riverton stay apart",
    subtitle = str_c(
      "Arrows point from subject to object and show the relation. ",
      "The bottom row contains nodes with no populated fact."
    )
  ) +
  theme_lesson(grid = "none") +
  theme(
    axis.text = element_blank(),
    axis.title = element_blank(),
    legend.key.size = unit(0.9, "lines")
  )

graph_plot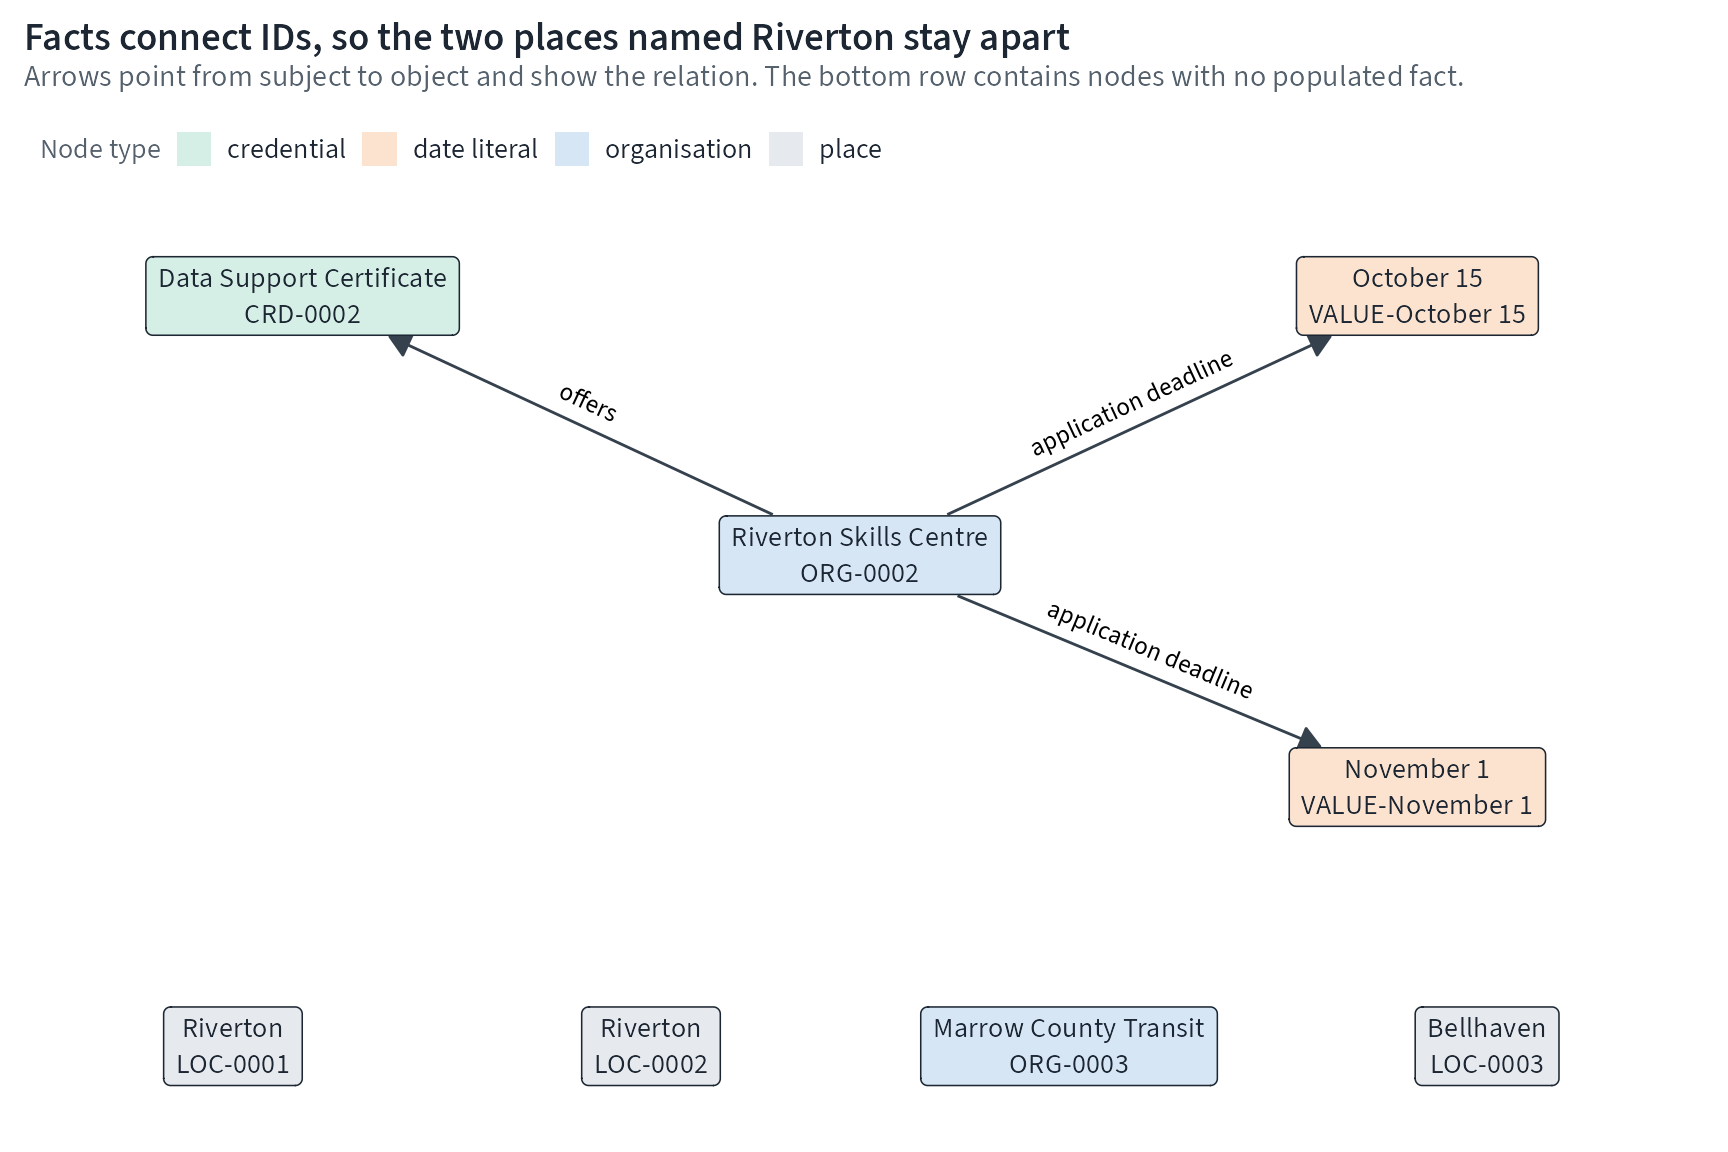
The relation labels are text, not colour. The arrowheads show direction, and the caption and table make the same information available outside the image. The fill colours group node types, and the ID prefix inside every label says the same thing in words.
Examine whether a layout seed changes only the picture
Force-directed layouts compute node positions with simulated attraction and repulsion. Their coordinates depend on random starting positions. A layout changes positions, not graph edges or degrees. A node’s degree counts its connections. The code computes two seeded Fruchterman-Reingold layouts. It compares coordinates for equality without printing them.
layout_for_seed <- function(graph, seed) {
  set.seed(seed)
  layout_with_fr(graph, weights = NA)
}

coordinates_identical <- identical(
  layout_for_seed(id_graph, 17L),
  layout_for_seed(id_graph, 29L)
)

coordinates_identical
[1] FALSEFALSE means the two seeds place the same eight nodes at different coordinates. Use the manually positioned figure to follow labelled arrows. The seed comparison shows why coordinates are not facts about relationships.
Build a co-word network for comparison
A co-word network has words as nodes. Its undirected edges represent how often words appear in the same unit, here an inaugural paragraph. The word rule retains alphabetic tokens of four or more letters. It converts them to English lowercase and removes tidytext stop words. Each word counts once per paragraph, regardless of additional occurrences.
paragraphs <- inaugural_paragraphs()

paragraph_words <- paragraphs |>
  transmute(paragraph_id, paragraph) |>
  unnest_tokens(word, paragraph, token = "regex", pattern = "[^A-Za-z]+") |>
  mutate(word = str_to_lower(word, locale = "en")) |>
  filter(nchar(word) >= 4L) |>
  anti_join(stop_words, by = "word") |>
  distinct(paragraph_id, word)

top_words <- paragraph_words |>
  count(word, name = "paragraphs_with_word", sort = TRUE) |>
  slice_head(n = 10)

top_word_presence <- paragraph_words |>
  semi_join(top_words, by = "word")

word_pairs <- top_word_presence |>
  inner_join(top_word_presence, by = "paragraph_id", relationship = "many-to-many") |>
  filter(word.x < word.y) |>
  count(word.x, word.y, name = "observed") |>
  left_join(top_words, by = c("word.x" = "word")) |>
  rename(first_paragraphs = paragraphs_with_word) |>
  left_join(top_words, by = c("word.y" = "word")) |>
  rename(second_paragraphs = paragraphs_with_word) |>
  mutate(
    total_paragraphs = n_distinct(paragraphs$paragraph_id),
    expected = first_paragraphs * second_paragraphs / total_paragraphs,
    observed_expected_ratio = observed / expected
  )

ratio_threshold <- 1.80
coword_edges <- word_pairs |>
  filter(observed_expected_ratio >= ratio_threshold) |>
  arrange(desc(observed_expected_ratio), word.x, word.y)

undrawn_words <- setdiff(top_words$word, c(coword_edges$word.x, coword_edges$word.y))| Word | Paragraphs with word |
|---|---|
| people | 409 |
| government | 358 |
| nation | 268 |
| country | 259 |
| world | 251 |
| citizens | 196 |
| time | 189 |
| peace | 172 |
| power | 169 |
| america | 167 |
| First word | Second word | Observed paragraphs | First word paragraphs | Second word paragraphs | Total paragraphs | Expected under independence | Observed / expected |
|---|---|---|---|---|---|---|---|
| peace | world | 68 | 172 | 251 | 1377 | 31.4 | 2.17 |
| america | world | 58 | 167 | 251 | 1377 | 30.4 | 1.91 |
| citizens | country | 70 | 196 | 259 | 1377 | 36.9 | 1.90 |
Raw co-occurrence among these ten frequent words forms a complete graph: all 45 pairs occur in at least one paragraph. The author chose the threshold for this lesson. It retains 3 pairs and excludes 42 pairs.
The observed count must be at least 1.8 times the expected count under independence. That expected count is count(word A) * count(word B) / paragraphs. The excluded top-ten words are people, government, nation, time, power.
Draw the co-word graph
The co-word graph uses the same ggraph grammar, but its edges are not typed facts. They are paragraph-level co-occurrences that passed the threshold. Each edge shows its observed-to-expected ratio instead of a relation.
# Listing the words edge by edge puts linked words next to each other on the
# circle, so no two edges cross.
coword_nodes <- tibble(
  name = unique(as.vector(rbind(coword_edges$word.x, coword_edges$word.y)))
)

coword_graph <- tbl_graph(
  nodes = coword_nodes,
  edges = coword_edges |>
    transmute(
      from = word.x,
      to = word.y,
      ratio_label = sprintf("%.1f×", observed_expected_ratio)
    ),
  directed = FALSE
)

coword_plot <- ggraph(coword_graph, layout = "circle") +
  geom_edge_link(
    aes(
      label = ratio_label,
      start_cap = label_rect(node1.name, fontsize = 12, fontfamily = lesson_font),
      end_cap = label_rect(node2.name, fontsize = 12, fontfamily = lesson_font)
    ),
    angle_calc = "along",
    label_dodge = unit(3, "mm"),
    label_size = 3.3,
    family = lesson_font,
    edge_colour = lesson_colours[["body"]],
    edge_width = 0.6
  ) +
  geom_node_label(
    aes(label = name),
    family = lesson_font,
    size = 4.2,
    fill = lesson_colours[["paper"]],
    colour = lesson_colours[["ink"]],
    label.padding = unit(0.3, "lines")
  ) +
  coord_cartesian(clip = "off") +
  scale_x_continuous(expand = expansion(mult = 0.15)) +
  scale_y_continuous(expand = expansion(mult = 0.15)) +
  labs(
    title = str_c(
      "Only ", nrow(coword_edges), " of ", nrow(word_pairs),
      " frequent word pairs pass the threshold"
    ),
    subtitle = "Undirected edges between words that share paragraphs at least 1.8 times as often as expected"
  ) +
  theme_lesson(grid = "none") +
  theme(axis.text = element_blank(), axis.title = element_blank())

coword_plot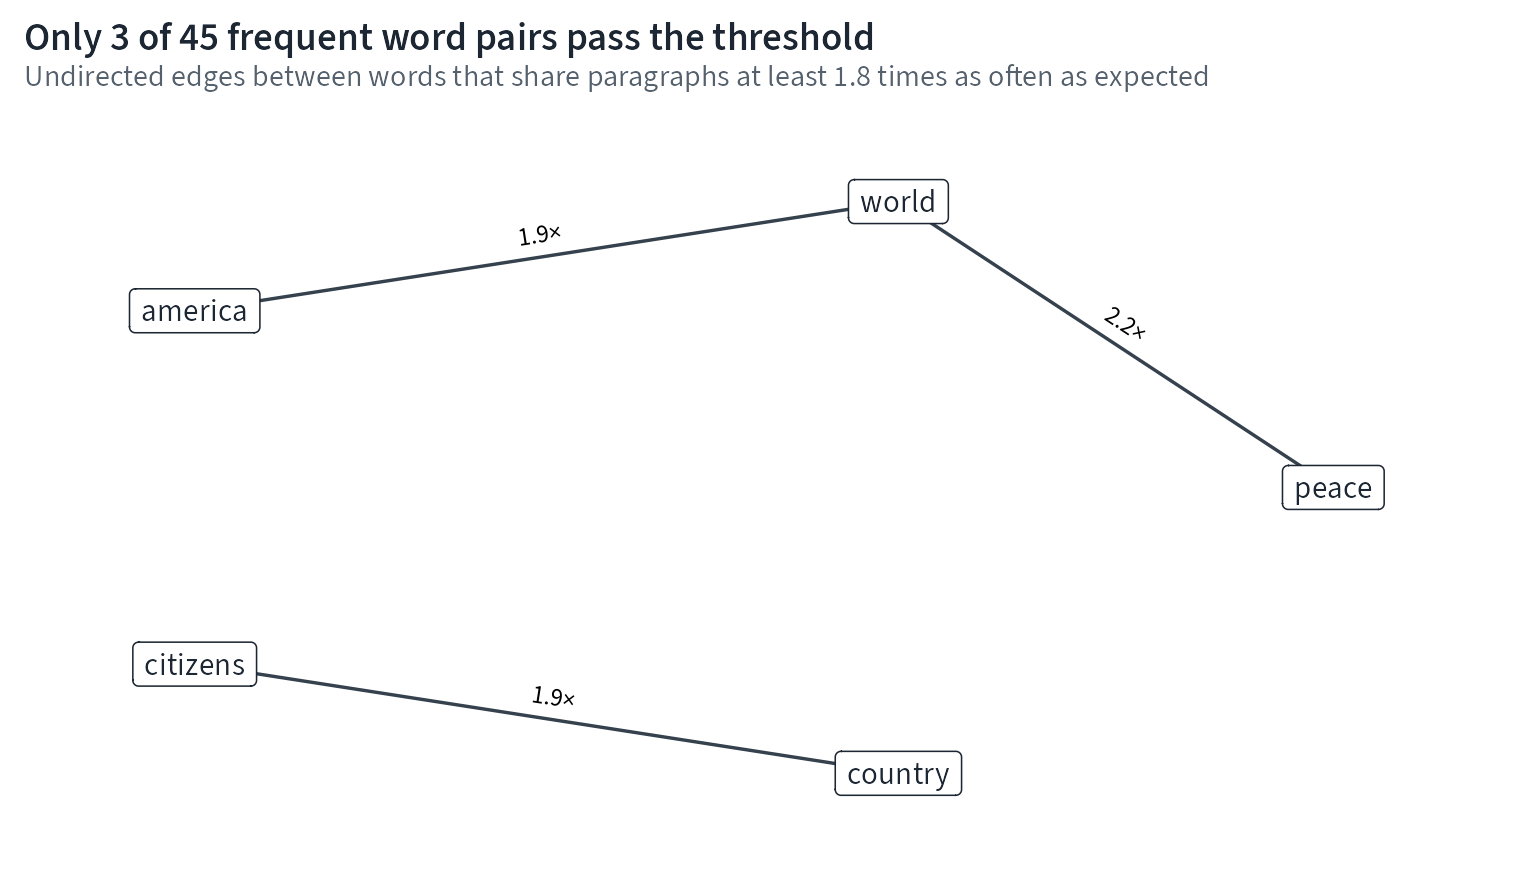
Unlike the Riverton knowledge graph, this co-word network has no entity IDs, no relation types, and no direction. It shows which word pairs remain after a preprocessing and threshold decision. It cannot say that the words mean the same thing or that one caused the other to appear.
What to remember
- Use stable IDs as node keys. Distinct nodes can share a label.
- The two
Rivertonplaces merge if labels are treated as IDs. - A force-directed layout is a computed drawing, not a measurement.
- Arrowheads and relation labels represent graph relationships.
- The edge-list table is part of the graph’s text alternative.
- Co-word edges are thresholded co-occurrences, not typed knowledge-base facts.
Read the edge table first. Use the drawing to follow the paths listed in that table.
Sources
- Hogan et al. (2021), Knowledge Graphs
- Fruchterman and Reingold (1991), Graph Drawing by Force-directed Placement
- ggraph documentation
- tidygraph documentation
- igraph
layout_with_fr()reference - McGrath, Blythe, and Krackhardt (1997), The effect of spatial arrangement on judgments and errors in interpreting graphs
- W3C WAI tutorial on complex images
- WCAG 2.2 Understanding Success Criterion 1.1.1
- Rip and Courtial (1984), Co-word maps of biotechnology
- van Eck and Waltman (2009), How to normalize cooccurrence data